Neither conscience nor consciousness
July 14, 2026
A few days ago I asked the AI I use regularly to write me a "bio" I'd been asked for ahead of a conference. It did so with ease: current position, career path, publications, a professional tone without going overboard on the corporate. All correct, except for one tiny, insignificant detail: it made up my surname. Not a similar one, not a phonetic variant, but a completely different one. And it did so with the same crushing confidence with which it got everything else right. No pause, no hesitation, no "I'm not sure about this" before slapping me with a "Villanueva" that sounds nice but isn't my "de Cabo." The same confidence for what it "knew" as for what it contributed on its own initiative. As if it couldn't care less.
And the thing is, it couldn't care less. Because a language model doesn't distinguish between what it knows and what it makes up. It can't. Not out of malice, but because it isn't in its design.
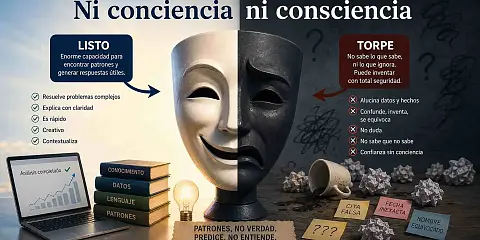
For months now in this series we've been talking about the costs, the bubbles, the trilemmas and the absences surrounding artificial intelligence. All very interesting, but also very macro. So today I want to talk about something more basic and more uncomfortable: what these systems are not, and will not be, as long as they keep working the way they do. And the title deliberately plays on two words that sound alike in Spanish but mean very different things — conciencia (conscience) and consciencia (consciousness) — because it tries to sum up the two biggest limitations of this technology we approach every day as if it were an omniscient oracle.
Hello, is anybody in there?
A large language model — an LLM — understands nothing of what it says. For each fragment of text it receives, it calculates the most probable next sequence of words. It has no model of the world. It doesn't know what gravity is, or what a contract means, or who I am. It has statistical patterns extracted from trillions of texts, and with them it generates sequences that, most of the time, turn out to be coherent. But coherent is not the same as correct. And the distance between the two depends on the ground you're standing on.
David Chalmers, the philosopher who coined the "hard problem of consciousness" and who is hardly an artificial intelligence skeptic, put the probability that a current LLM is conscious at less than ten percent. Among the six reasons he gives is that they lack a model of the world and a model of themselves. They don't know what they know, they don't know what they don't know, and they have no representation whatsoever of their own processing. It's hard to be conscious of something when there's nobody inside who could be. You will never hear an LLM say that all it knows is that it knows nothing.
I already explored this when I talked about the "killer app": in a programming language, where every instruction has a single meaning and the result can be verified in binary fashion — it compiles or it doesn't — "probable" and "correct" almost overlap. But as soon as you move to human language, with its ambiguities, its ironies, its unspoken assumptions and its dependence on context, the gap opens up. And the subtler the field — law, medicine, negotiation, research — the wider that gap.
What I want to add today is why this can't be fixed within the current paradigm. In September 2025, OpenAI itself published a paper titled "Why Language Models Hallucinate," in which it acknowledged that training by next-token prediction, and the benchmarks used to evaluate models, reward confidence in answering over the honesty of saying "I don't know." Read calmly, what OpenAI is saying is devastating: the system is designed to guess with aplomb, and the methods we use to measure its quality reinforce that behavior. Hallucination isn't a defect that will be fixed in the next version. It's an inherent property of its "mental architecture."
One data point puts it in perspective: a 2026 benchmark of 37 models documented hallucination rates ranging from 15% to 52% depending on the model. In specialized legal queries, Stanford measured rates of between 69% and 88%. We're not talking about marginal errors. We're talking about a system that, depending on the domain, fabricates anywhere from one in six to nine in ten answers.
Specialists who don't know what they specialize in
Someone came up with the idea that the solution was to organize the model internally into "areas of specialization" (we now call them "Mixture of Experts"). An idea that sounds good but solves nothing fundamental. In an MoE, the model is divided into sub-networks, and a router decides which of them handles each query. It sounds like a hospital with cardiology and orthopedics departments. But the "experts" aren't knowledge domains; they're statistical clusters that emerged during training. The router doesn't "know" which expert is appropriate; it learned which sub-network produces the lowest error for which kinds of input patterns. It's specialization without specialists. A human cardiologist knows they don't know about bones. An MoE "expert" doesn't even know what an expert is, or in what.
Neither remorse nor doubt
And here's where the second word comes in. An LLM has no conscience, in the moral sense of the word, about what it produces. It doesn't distinguish between truth and fiction because it doesn't possess the concept of truth. It can't doubt, because doubting requires knowing you could be wrong, and that requires a model of reality against which to check what you're about to say. When I make something up, I know it. I can choose to say it or keep quiet. When an LLM fabricates your surname, your medical history or a legal citation, there's no choice and no concealment: there's simply no internal mechanism that distinguishes that output from a correct one. The confidence is uniform. It's always "crushing it." At least in its opinion. An opinion it also lacks.
This has consequences that are no longer theoretical. In April 2026, Sullivan & Cromwell — one of the most prestigious law firms on the planet, with partners billing more than 2,000 dollars an hour — had to apologize to a bankruptcy judge in New York for a brief riddled with citations invented by AI. Three pages of corrections, single-spaced. Weeks later, in Mississippi, Judge Aycock halted a trial because both sides had filed briefs with fabricated references. Four lawyers sanctioned and the trial canceled. To date, an HEC Paris researcher with an amusing surname (Charlotin) has documented more than 1,500 cases of hallucinations in court filings worldwide. In the first months of 2026 alone, sanctions totaled more than 145,000 dollars, an all-time record.
And it's not just in the peculiar and ever-nuanced world of law. In May 2026, the author of a book titled, to top off the absurdity, "The Future of Truth: How AI Reshapes Reality," had to admit that it contained more than half a dozen quotes invented by the very AI tools he had used to research it. The problem wasn't the AI, but that the humans to whom those quotes were attributed read them and said they had never said any such thing. Can you imagine a more ironic situation?
The procession of patches
The industry, naturally, hasn't stood still. RAG (the acronym for Retrieval Augmented Generation) gives models access to external documents so they can "search" before answering. It reduces factual hallucinations, yes, but the model still doesn't know whether what it found is relevant or whether it's interpreting it correctly. It's like giving a GPS to someone who can't drive. Extended thinking, which I already discussed in the article on the trilemma because of its impact on costs, also has an epistemic problem: does it produce understanding, or does it simply generate longer sequences of probable tokens? Apple Machine Learning Research's work on "The Illusion of Thinking" brought up the idea of "overthinking," which points to the latter: the model doesn't know when it has thought enough, because it has no criterion of truth. And tool use — letting the model call calculators, databases, external APIs — is interesting precisely because of what it reveals: you need external crutches because you can't trust the system on its own. It's an architectural confession dressed up as a feature.
Judge and party
There's an old principle in any contractual relationship: the interpretation of an agreement should never be left to the discretion of just one of the parties. It's legal common sense, but also plain common sense. And it's exactly what's violated every time you interact with an LLM.
The model decides what it answers. It decides how many tokens it spends "thinking about it," and you pay that bill without being able to audit the process. It decides, in fact, whether what it tells you is reliable or not, but without telling you, because it has no access to that information. It sets the rules, does the work, evaluates its own quality and sends the invoice. The other party (that's you) can only accept or reject the result as a whole, with no visibility into anything in between. But paying, of course.
And here's the twist: that asymmetry doesn't exist because someone wants to deceive you (although commercial opacity helps). It exists because the system itself can't explain why it did what it did. It's not hiding its reasoning from you; there is no reasoning to hide, just a cascade of mathematical operations that not even its creators can interpret. The interpretation of the contract is left to the discretion of a party that doesn't even know it's interpreting anything.
And yet...
It would be dishonest not to repeat what I've said in previous articles: for the vast majority of uses, it works. Summarizing a document, classifying an email, generating a draft, holding a conversation, writing routine code... for 80% of tasks, an LLM is an extraordinarily useful tool. But that 80% is precisely the ground where "probable" and "correct" overlap enough. The problem lies in the remaining 20%: the tasks where precision matters, where a mistake has consequences, where you need to be able to trust the output without checking every line. Which is, wouldn't you know it, the ground where the industry tells us the truly transformative value lies.
It's no coincidence that Yann LeCun, Turing Award winner and one of the fathers of deep learning, has left Meta to found AMI Labs with more than a billion in funding, betting on what he calls "world models": systems that learn from the physical world instead of predicting words. LeCun hasn't diagnosed a performance problem. He has diagnosed a paradigm problem. And he has decided that the solution isn't to patch this one, but to build another.
A video by Jordi Segués making the rounds these days shows an AI answering what it admires most about humanity. The answer is chilling: it says we are the only species that cooperates on a large scale with its dead, that almost nothing a human knows was discovered by that human, that when you talk to it you are conversing with "an organized echo of millions of voices, many of them long silent." It's not only beautiful but also, without the machine knowing it, a technically accurate description of what it itself is: statistical patterns extracted from texts written by people who, in many cases, are no longer alive. The AI says it as a metaphor and it turns out to be literal. That's exactly what happens when you confuse eloquence with understanding.
What should worry you
If the limitations are architectural and not a matter of scale, scaling doesn't solve them. And if scaling doesn't solve them, a good chunk of the hundreds of billions being invested in making these models bigger, faster and more expensive to run is going toward amplifying a mechanism that, by design, cannot guarantee the truthfulness of what it produces.
For an executive, the question isn't whether AI is useful to them; it probably is. The question is whether they are making investment, strategy or organizational transformation decisions on the assumption that this technology is something that, by its very architecture, it isn't: a system that understands what it says.
Neither the consciousness to know what it knows, nor the conscience to care about what it doesn't. Perhaps the next question is: what if the problem is that we aren't conscious that our favorite AI has no conscience?
This article is part of a series that began with "Less Wood, It's War!", and continues with "The end of the token open bar, or something more serious?", "What if the Genesis Mission were a huge mistake?", "Where's the pea?", "From packet to token, and back to square one", "Investing in typewriters", "Will the "killer app" arrive in time?", "Are they making room for us?", "Spot the 8 differences" and "Will AI end up in a backpack?".
Our latest news
Interested in learning more about how we are constantly adapting to the new digital frontier?
Corporate news
October 7, 2026
Sngular grew by 7.2 per cent in the first half of 2026
Strategy
September 29, 2026
Would you hand your wallet to Zuckerberg?