Will AI end up in a backpack?
June 23, 2026
A few weeks ago, while preparing a class on technology investment, I asked a student to work out something simple for me: if you multiply the investment in training an AI model by ten, how much does the result improve? The intuitive answer was "a lot." The real answer is between one and two percentage points on the standard benchmarks.
It's worth pausing here. Because I don't know whether that figure changes the entire conversation about AI, but it certainly changes the perception that non-professional readers have of it. So let's start with some data to help put things in perspective.
In 2020, training GPT-3 cost on the order of five million dollars. In 2023, GPT-4 came to around eighty million in pure compute (and Sam Altman admitted it topped a hundred million once everything was added up). In 2025, Grok-4 cost xAI some five hundred million, according to Epoch AI estimates. In other words: the cost of building what the industry jargon calls "frontier models" has multiplied a hundredfold in the five years it took AI to become part of the collective imagination. But the improvement that such an investment effort brought with it, in terms of what a model can actually do, has gone from leaps of dozens of points to baby steps of one or two. The investment curve is exponential, but the improvement curve is asymptotic. And between the two a gap opens up that no business plan can sustain indefinitely.
That's what Hemant Shukla documents in his analysis of the "Scaling wall of diminishing returns": multiplying compute capacity by ten now buys just one or two percentage points of improvement on the standard benchmarks. And let's not forget that this happens on top of investment amounts that are already obscene to begin with.
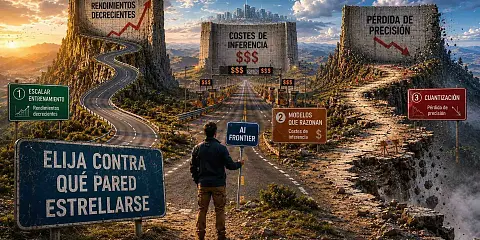
That's a first wall, impossible to get over as things stand today.
But... if it reasons better, you can charge more for it, right?
The industry's response to this first wall has been elegant in its simplicity: "All right, training is reaching a saturation point. But now we have models that reason in real time —thinking models— that improve their answers by spending more compute at inference time, not in training." That's the thesis of OpenAI with its O series, of Anthropic with its extended thinking, or of DeepSeek with R1, to mention just three examples of the trend. And it works: results in mathematics, code and complex reasoning genuinely improve when the model "thinks longer."
The problem is the price. A query processed by a thinking model consumes between ten and a hundred times more compute than a conventional chat query, in a range that the most rigorous studies put at between 10x and 74x on the AIME benchmark. That's not a marginal increase. It's a change in order of magnitude. And if inference is (as it should be, if AI ends up being a success) the bulk of the future business, what we're doing is replacing a wall of training costs with a wall of inference costs. The bill moves somewhere else, but it doesn't go away. And nobody gets to skip it.
Analysts such as Brookfield project that inference will claim 75% of total AI energy demand by 2030. Add to that the fact that reasoning models generate answers hundreds of times longer than conventional ones (because they "overthink" even simple tasks, as Apple Machine Learning Research has documented), and resource consumption scales in a way that invalidates the cost-reduction projections the industry (or the financiers who control it) has been selling for two years.
That's the second wall. And nobody gets over this one either.
The trap that springs itself
This is where things get really ugly.
Quantization, an insider's term that means reducing the numerical precision a model operates with, from 16 bits to 4, to 3, or even to 1, was conceived as the escape route. If you can't make training cheaper, at least make execution cheaper. And for simple tasks it works. A model quantized to 4 bits can summarize texts, classify emails or hold a conversation with an accuracy that is hard to tell apart from the full model.
But thinking models need more precision, not less. Multi-step reasoning — precisely the capability that justifies the extra cost of inference — is the first thing to degrade when you quantize. Data from Li et al. show up to a 32% drop in accuracy on mathematical reasoning tasks with aggressive quantization on "Llama-3" models. Admittedly, that figure is the worst documented case, but their average is around 11%, and their subsequent work raises the drop to 70% in extreme configurations. That's not a marginal effect. It's the difference between a model that solves a problem and one that hallucinates the solution.
In other words: you quantize to cut costs, but you destroy the one thing that justifies the cost. And let's see who gets over the third wall.
Three doors, all bricked up
Nobody in this industry has any interest in being the first to say it out loud, but all three paths to sustaining the business model are blocked. Scaling training has proven diminishing returns: every hundredfold increase in investment buys an improvement that an ordinary user struggles to notice. Improving via inference with reasoning models works technically, but multiplies costs by a factor that makes the promised price reductions unfeasible. And quantizing to cut costs destroys precisely the capability that justifies the existence of the most advanced models. As I argued in "Where's the pea?", nobody in the chain has any interest in stopping to think whether there really is a pea.
And yet, for you, it probably works
It would be dishonest not to acknowledge one thing: for the vast majority of business uses, the problem doesn't exist. An efficient model running locally — quantized, yes, but for tasks that don't demand deep reasoning — more than covers 80% of the work: summarizing documents, classifying information, generating drafts, automating the repetitive stuff. You don't need a frontier model to answer emails. If you're a CTO who has deployed AI in your company and it works for you, congratulations. It works for you. But that is exactly what makes the trilemma more devastating, not less.
To complicate the assessment even further, Nvidia has just put on the table a desktop box with a Blackwell processor and 128 gigabytes of unified memory, capable of running a 120-billion-parameter model without going through the cloud. Or, put another way: without needing the extremely expensive data centers in which its customers are installing those very same processors by the truckload. Surprising, isn't it? Although it's worth reading the fine print: that model runs there because it's quantized to 4 bits. What fits in the backpack isn't a frontier model, it's the "good enough" we've been talking about: brilliant for 80% of tasks, and aimed at users who don't mind it crashing into the third wall on the 20% that genuinely requires reasoning. The gadget that seems to make datacenters unnecessary turns out to be the best proof of where the limit lies. And it can't be such a crazy idea, because AMD —its historic rival— already sells boxes with equivalent memory at a lower price, and has just unveiled its own, undercutting Nvidia's by seven hundred dollars. A telling sign that the hardware makers aren't entirely confident about the future of the super-datacenters, and are hedging their bets by lighting one candle to God and another to the devil.
But the thing is, if "good enough" covers 80% of use cases —and as we saw in "What if the Genesis Mission were a huge mistake?", my daughter already confirmed it with a Chinese model that cost her nothing—, then the hundreds of billions invested in frontier infrastructure are being spent to serve the remaining 20%. A 20% for which, as we've just seen, there is no clear path to improvement at a reasonable cost.
The massive investment in datacenters, in GPUs, in ever larger models, rests on the premise that the frontier will keep advancing and justify the spending. The data say it won't. And when the frontier stops advancing but the investment doesn't stop, what you have isn't innovation. It's inertia. Inertia with a price tag of hundreds of billions of dollars.
How long can the most expensive industry in history keep up the race when all three doors are bricked up and what actually works already fits in a backpack?
And the backpack will get smaller as Moore's law runs its course. Perhaps AI will end up in a backpack. Perhaps it will end up in a pocket.
What I don't know is who is going to pay the hundreds of billions needed to keep pushing the frontier when most of the value can already run locally.
And that, more than a technological question, is an economic one.
This article is part of a series that began with "Less Wood, It's War!", and continues with "The end of the token open bar, or something more serious?", "What if the Genesis Mission were a huge mistake?", "Where's the pea?", "From packet to token, and back to square one", "Investing in typewriters", "Will the "killer app" arrive in time?", "Are they making room for us?", "Spot the 8 differences". To be continued...
Our latest news
Interested in learning more about how we are constantly adapting to the new digital frontier?
Corporate news
October 7, 2026
Sngular grew by 7.2 per cent in the first half of 2026
Strategy
September 29, 2026
Would you hand your wallet to Zuckerberg?